Saved
Systems · Semiconductors

AI data center

AI data centers don’t just run models—they starve the rest of computing of memory.

Worth your time?4/5Yes.Study the whole thing.What works, what does not, who it is for ↓
11:49in productionCh. 1 · What it is/ 11:49 · ceiling 15 min
4 chapters · 11:49Ceiling 15:00

The brief is written and checked. The video joins this page when it is cut.4 chapters · 1 min read · 11:49 planned

Read the brief

AI data centers are real, operational, and materially disruptive—not speculative infrastructure. They deliver AI compute but at the cost of memory scarcity, power strain, and wafer allocation shifts that are already visible in global supply chains.

Chapters & takeaways4
  1. 1:08
    What it is

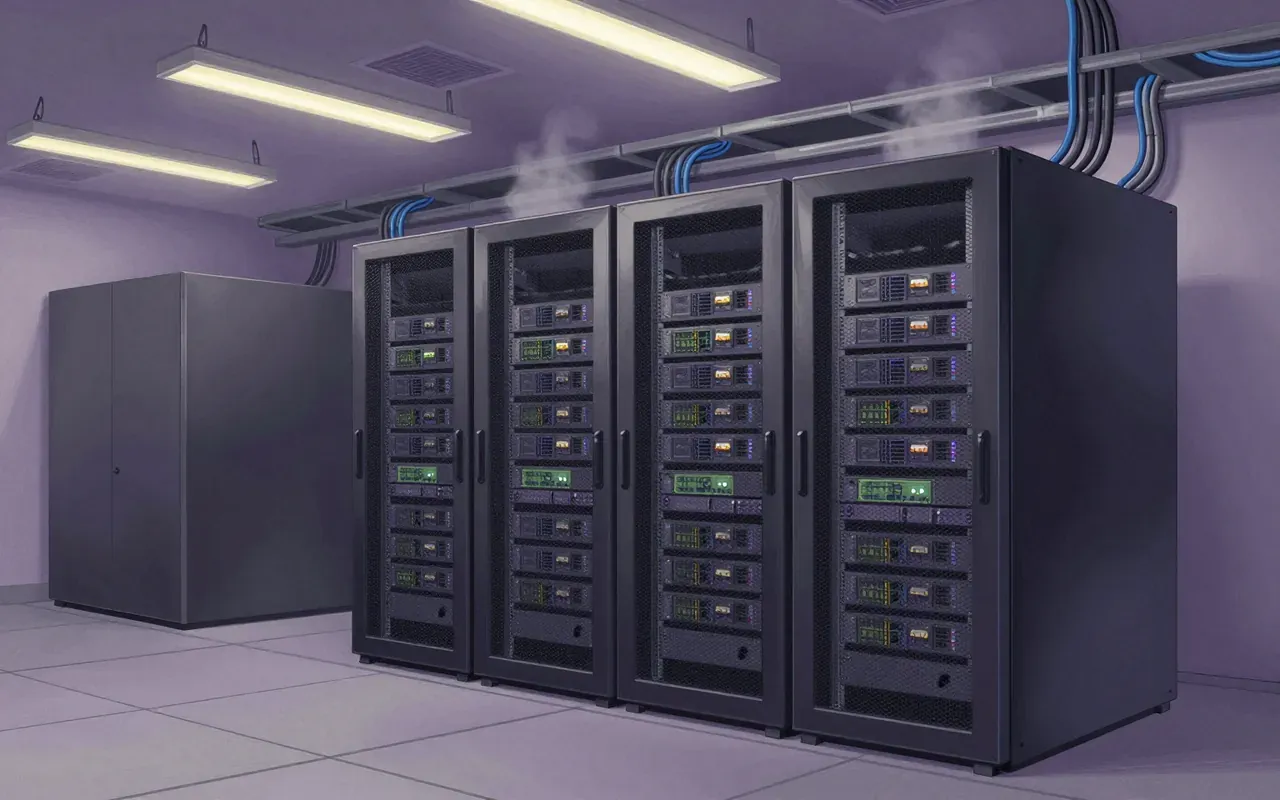
    AI data centers are purpose-built for parallel AI workloads—not general computation.

  2. 2:34
    Power density

    They consume six times more power per rack than general-purpose data centers.

  3. 4:33
    Memory bottleneck

    HBM fabrication uses three times the wafer capacity of DDR5—and has exhausted global memory supply since 2024.

  4. 6:33
    Supply chain capture

    70% of global memory output in FY2026 goes to AI data centers—and one project takes 40% of all DRAM wafers.

1 more chapterFewer chapters
Worth your time?

Yes. Study the whole thing.

4/ 5
What works
  • parallel AI workload execution
  • DRAM and HBM allocation at scale
  • rack-level thermal and power delivery
What does not
  • solve memory scarcity
  • scale without fabrication trade-offs
  • operate within general-purpose power infrastructure
Study it if
  • chipmakers
  • utility planners
  • memory procurement teams
Skip it if
  • application developers without infra constraints
  • end users of AI services
  • policy analysts without technical supply-chain focus
Who should study it, and who should skipHide who it is for
The written brief1 min read

What it is and the problem it solves

An AI data center is a specialised facility for training and running AI/ML models. It solves the problem of executing massively parallel AI workloads—but only at the cost of extreme power density and memory scarcity.

How it works

AI data centers use AI accelerators and high-speed interconnects to handle parallel AI workloads. They draw ~60 kW per rack—six times the power load of general-purpose data centers, which use ~10 kW per rack.

What works

The hardware stack—accelerators, interconnects, and high-bandwidth memory—enables viable AI model training and inference at scale. Power and memory demand are not theoretical; they are measured, deployed, and constraining.

What does not

They do not scale without straining global memory supply. Their construction since 2024 has exhausted global computer memory supply. HBM production consumes three times the wafer capacity per bit of DDR5, worsening the bottleneck.

What it changes

They shift memory production: 70% of global computer memory output in the 2026 fiscal year is allocated to AI data centers. The Stargate project alone takes ~40% of global DRAM wafer output—900,000 wafers per month.

Is it worth your time

Yes—if you manage memory supply chains, power infrastructure, or semiconductor fabrication. No—if your work is unaffected by DRAM allocation, wafer capacity, or rack-level thermal design.
Same field · Systems4 of 192
9:58
Multiplayer video gameA multiplayer video game is a coordination system—not a genre, not a platform, not an experience. It forces explicit decisions about timing, authority, visibility, and failure mode. Its history is one of repeated adaptation to infrastructure limits, not creative evolution.
9:48
RedisSalvatore Sanfilippo · 2009Redis is an in-memory key-value database introduced in 2009 by Salvatore Sanfilippo to solve scalability issues at his startup LLOOGG. It delivers low-latency operations by holding all data in memory and using the fork system call to enable concurrent client service and disk persistence. It supports two persistence methods—RDB snapshotting and AOF journaling—with journaling introduced in version 1.1 and considered safer. Default configuration limits data loss to a few seconds upon full system failure. Redis supports master-replica replication with hierarchical trees and introduced clustering in April 2015 with version 3.0. It grew into one of the world’s most popular databases for caching, message brokering, and primary storage. In December 2024, Sanfilippo returned to Redis and implemented the Vector Set data structure for vector similarity search.
10:43
Apache KafkaLinkedIn · 2010Kafka is a distributed, open-source event store and stream-processing platform developed at LinkedIn and open sourced in early 2011. It uses a binary TCP-based protocol and a 'message set' abstraction to optimise efficiency, enabling linear writes from bursty streams. It guarantees ordering within partitions, retains messages in a durable append-only log, supports manual offset management, and introduced share groups in 2025 for queue-like semantics. Kafka Connect and Kafka Streams were added in versions 0.9.0.0 and 0.10.0.0 respectively.
10:00
App Store (Apple)2008The App Store is Apple’s controlled app distribution system. It launched with 500 apps on July 10, 2008. It now hosts over 1.9 million apps. It enforces mandatory review, a 30% revenue cut, and platform-specific restrictions—relenting only under regulatory pressure, as with EU-mandated game streaming access in January 2024.
Up next in Technology

Amiga 500

Commodore · 1987 · 10:53

The Amiga 500 didn’t invent home computing—it redefined what a home computer was allowed to do.

10:53